Web Scraping Services
Web scraping and data extraction that stays reliable
Scraping a page once is easy. Getting clean, deduplicated data every week from sites with dynamic content and pagination is the actual job. I build scrapers and extraction pipelines with Playwright, Apify, Python, and browser extensions that deliver structured data in the format you need, and keep doing it.
Who this is for
- Marketing and sales teams building verified prospect or partner lists
- E-commerce teams importing or monitoring product catalogs
- Research and ops teams collecting data that only exists on web pages or PDFs
Problems I solve
- Days of copy and paste to build a list that is stale a month later
- Dynamic sites and pagination that break simple scrapers
- Raw data full of duplicates and malformed records
- Scraper subscriptions charging monthly for a job a script could do
What you get
What I build
Custom scrapers
Playwright or Selenium for dynamic sites, Apify actors, or lightweight Python for simple pages.
API enrichment
Scraped records verified and enriched against official APIs where they exist.
Browser extensions
Chrome extensions that extract from the live DOM, including parallel tabs and bulk imports.
Document extraction
PDF and OCR extraction for data locked in documents.
Clean delivery
Deduplicated, validated JSON, CSV, Google Sheets, or direct inserts to your database or endpoint.
Re-runnable pipelines
Scheduled runs that keep the dataset current, with alerts when a source changes.
Proof of work
Systems I've shipped
Real projects running in production, with the problem, the build, and the outcome.
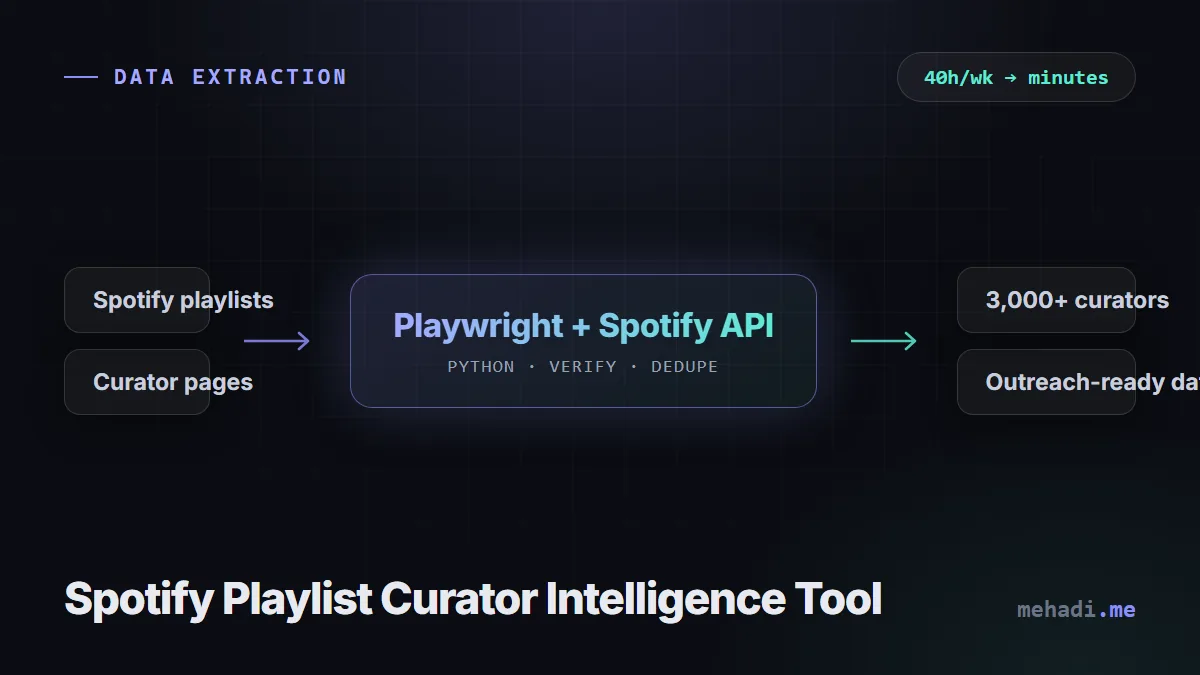
Automation · Data Extraction
Spotify Playlist Curator Intelligence Tool
Playwright + Spotify API automation that compiled 3,000+ verified playlist curators, cutting 40 weekly research hours down to minutes.
- 3,000+ verified playlist curators compiled
- Manual research cut from 40+ hours per week to minutes
Browser Extension · Scraping
E-commerce Data Extraction Extension
A Chrome extension that turns product listings into clean, structured JSON, pagination, bulk import and all.
- Full product catalogs collected in hours instead of weeks
- Data arrives clean and structured, with no post-processing needed
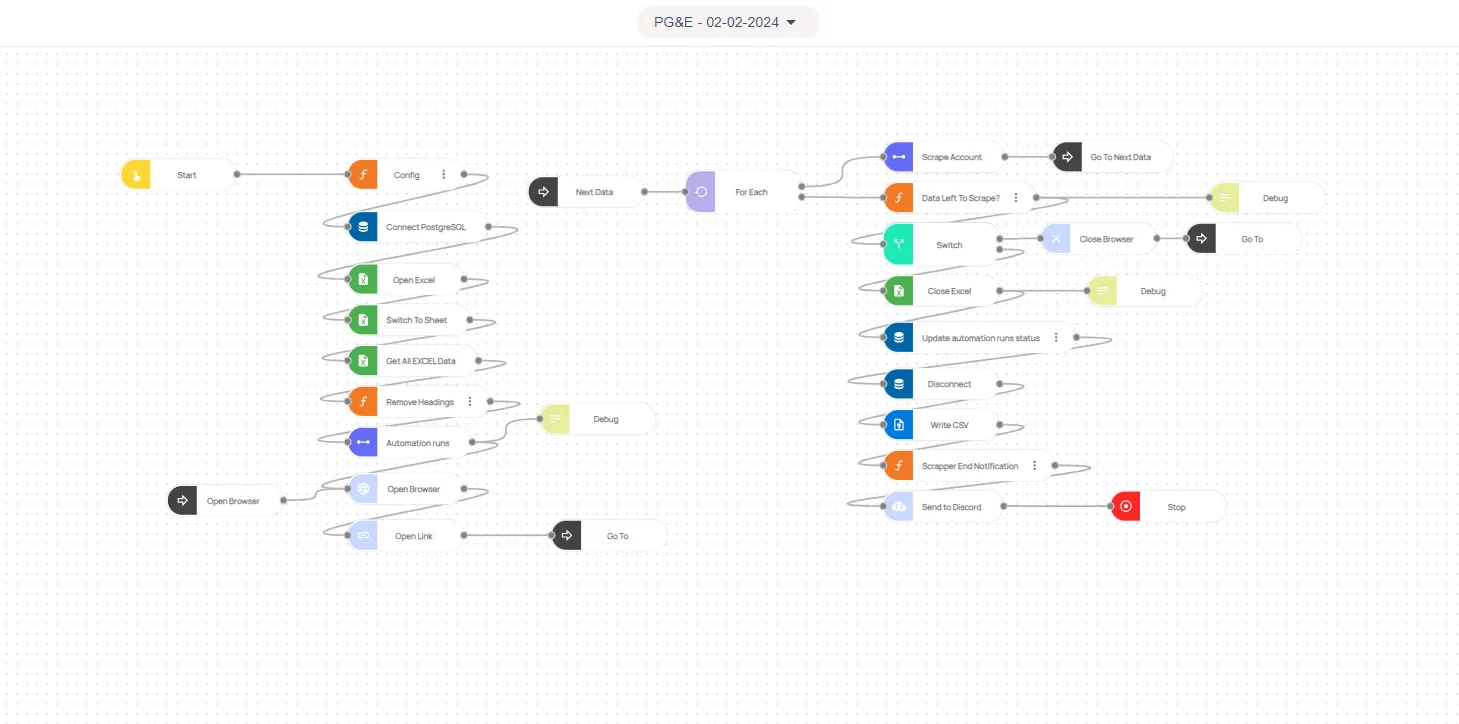
RPA · Data Pipeline
Utility Bill Data Pipelines (PG&E + SFWater)
Unattended bots that retrieve, OCR, and archive hundreds of utility PDFs from two providers, with no human in the loop.
- Bill retrieval and data entry became fully hands-off for both providers
- One clean, queryable database across PG&E and SFWater
How it works
From first call to running system
-
01
Free 30-min audit
You walk me through the manual process. I tell you honestly whether automation makes sense and roughly what it involves.
-
02
Fixed-scope proposal
If it is a fit, you get a written scope, timeline, and price before any work starts. No obligation.
-
03
Build and test
I build with error handling, retries, and alerting from day one, and test against your real data and edge cases.
-
04
Handover and support
You get documentation and a walkthrough, plus optional maintenance for when sites, APIs, or credentials change.
Good to know
Questions about Web Scraping & Data Extraction
Is web scraping legal?
Collecting publicly available data is generally allowed in many jurisdictions, but terms of service, personal data rules such as GDPR, and copyright all matter. I scope each project with that in mind and will flag sources or uses that look risky. This is not legal advice.
What format will I get the data in?
Whatever your next step needs: JSON, CSV, Google Sheets, direct database inserts, or a POST to your API.
What if the site changes its layout?
Scrapers validate what they collect and alert when results look wrong, so a layout change is caught quickly. Maintenance plans cover the fixes.
Tell me what's eating your team's hours
Describe the manual process and the tools involved. I'll reply within 24 hours with an honest take on whether automation can fix it, what it would involve, and what it would cost.